Sponsored LinkedIn post
A dedicated post to introduce your brand to my audience.
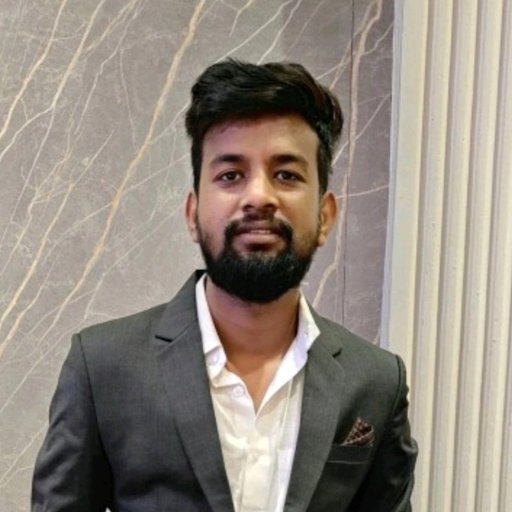
Data Engineering Creator @ YouTube
Companies pay Shubham to write a post about their product on LinkedIn.
This page is where they book it. Below: Shubham's audience, recent posts and price. Naano, the platform behind this page, handles the brief, your approval of the post and the payment.
€575per post, fixed price
You approve the post before it goes live
Looking for Shubham? View LinkedIn profileA creator yourself? Create your own page
300K @LinkedIn | Data Engineer | Data Analytics | AWS, Azure, GCP.
For collabs - [email removed]
My most engaged audience
62% Senior IC · 68% Engineering / Data
From 217 people who reacted to or commented on my posts
Public LinkedIn data · Sep 17, 2026
Shubham Wadekar
I’ve seen people go from TCS (3.36 LPA) ⇾ Deloitte (24 LPA+) I’ve seen people go from Infosys (3.5 LPA) ⇾ KPMG (27 LPA+) I’ve seen people go from Wipro (4 LPA) ⇾ PwC (29 LPA+) All because they focused on improving their Data Engineering skills: ❌ They didn’t only focus on theory without coding ❌ They didn’t stop after one small demo pipeline ❌ They didn’t waste time on too many certificates Instead, they: ✅ Got strong in basics – SQL, Python, data modeling ✅ Learned how to save cost on cloud tools ✅ Practiced scaling from small data to big data ✅ Built small real projects with free datasets ✅ Practiced fixing errors and making pipelines run faster ✅ Learned how big data tools/cloud really work (Spark, Azure) Because in Data Engineering interviews at Deloitte/KPMG, it’s not just about knowing tools. It’s about how you design, optimize, and explain a solution. 𝗜 𝗵𝗮𝘃𝗲 𝗽𝗿𝗲𝗽𝗮𝗿𝗲𝗱 𝗖𝗼𝗺𝗽𝗹𝗲𝘁𝗲 𝗜𝗻𝘁𝗲𝗿𝘃𝗶𝗲𝘄 𝗣𝗿𝗲𝗽 𝗚𝘂𝗶𝗱𝗲 𝗳𝗼𝗿 𝗗𝗮𝘁𝗮 𝗘𝗻𝗴𝗶𝗻𝗻𝗲𝗿𝘀. 𝗚𝗲𝘁 𝘁𝗵𝗲 𝗚𝘂𝗶𝗱𝗲 𝗵𝗲𝗿𝗲 - https://lnkd.in/gJWSVKNM 𝗠𝗮𝘆 𝗱𝗶𝘀𝗰𝗼𝘂𝗻𝘁 𝗲𝗻𝗱𝗶𝗻𝗴 𝘁𝗼𝗱𝗮𝘆 - AZURE30 / AWS30 / GCP30 only for next 5 people If you've read so far, do LIKE and RESHARE the post👍
Shubham Wadekar
2022: No salary increase 2023: No salary increase 2024: No salary increase 2025: Switched. 3x salary. 🚀 That’s how it went. • Same work. • Same effort. • Same results. I kept waiting for things to change. and they didn’t. That’s when I realized - effort isn’t enough, direction matters. So I stopped random prep and started following a plan. - Practiced real interview questions. - Revised concepts the right way. - Built consistency with a proper roadmap. And that changed everything. • New company. • New role. • 3x salary. That one switch gave me what 3 years of waiting couldn’t. If you’re in the same place I was, don’t just keep waiting. Start preparing the right way. 𝗞𝗲𝗲𝗽𝗶𝗻𝗴 𝘁𝗵𝗶𝘀 𝗶𝗻 𝗺𝗶𝗻𝗱, 𝗜 𝗵𝗮𝘃𝗲 𝗽𝗿𝗲𝗽𝗮𝗿𝗲𝗱 𝗖𝗼𝗺𝗽𝗹𝗲𝘁𝗲 𝗜𝗻𝘁𝗲𝗿𝘃𝗶𝗲𝘄 𝗣𝗿𝗲𝗽𝗮𝗿𝗮𝘁𝗶𝗼𝗻 𝗚𝘂𝗶𝗱𝗲 𝗳𝗼𝗿 𝗗𝗮𝘁𝗮 𝗘𝗻𝗴𝗶𝗻𝗻𝗲𝗿𝘀. 𝗚𝗲𝘁 𝘁𝗵𝗲 𝗚𝘂𝗶𝗱𝗲 𝗵𝗲𝗿𝗲 - https://lnkd.in/gJWSVKNM 𝗗𝗶𝘀𝗰𝗼𝘂𝗻𝘁 𝗲𝗻𝗱𝗶𝗻𝗴 𝘁𝗼𝗱𝗮𝘆 - AZURE30 / AWS30 / GCP30 only for next 5 people If you've read so far, do LIKE and RESHARE the post👍
Shubham Wadekar
I failed 3 Data Engineering interviews back-to-back. Fractal ❌ Mastercard ❌ PUMA Group ❌ All within 15 days. I had 4+ years of Data Engineering experience. I had built pipelines in production. I thought - “This should be easy" But interviews were a reality check. Same SQL, but the queries were trickier. Same Spark, but questions were deeper. Same resume, but I couldn’t connect it to real problems Same project, but couldn’t explain properly. 𝗛𝗲𝗿𝗲 𝗮𝗿𝗲 𝟯 𝗺𝗶𝘀𝘁𝗮𝗸𝗲𝘀 𝗜 𝘄𝗮𝘀 𝗺𝗮𝗸𝗶𝗻𝗴. 1. I studied tools, not concepts - I could explain what Databricks notebooks are, but not how to optimize jobs with partitions, caching, and cluster configs. - I knew Python syntax, but not how to write clean, modular code for data pipelines with error handling. 2. I assumed “I built it, so I can explain it.” Wrong. I struggled to frame my work. I wasn’t telling the story of → problem → design choice → impact. 3. I ignored fundamentals - SQL window functions, data partitioning, file formats, distributed joins That’s where most interview questions came from. 𝗪𝗵𝗮𝘁 𝗜 𝗰𝗵𝗮𝗻𝗴𝗲𝗱 𝗶𝗻 𝗺𝘆 𝗽𝗿𝗲𝗽𝗮𝗿𝗮𝘁𝗶𝗼𝗻: • I took my own pipelines and asked myself “Why did I design it this way?” • I wrote project explanations in a Q&A format, like I’m the interviewer. • I re-learned fundamentals: SQL, Spark internals, data modeling - not just tools. Next interview? Cleared ✅️ 𝗠𝗼𝗿𝗮𝗹? You don’t fail because you don’t know Spark or ADF. You fail because you don’t know how to explain your work like a data engineer. Everything comes from practice, reflection, and getting your hands dirty. 𝗜 𝗵𝗮𝘃𝗲 𝗽𝗿𝗲𝗽𝗮𝗿𝗲𝗱 𝗖𝗼𝗺𝗽𝗹𝗲𝘁𝗲 𝗜𝗻𝘁𝗲𝗿𝘃𝗶𝗲𝘄 𝗣𝗿𝗲𝗽 𝗚𝘂𝗶𝗱𝗲 𝗳𝗼𝗿 𝗗𝗮𝘁𝗮 𝗘𝗻𝗴𝗶𝗻𝗻𝗲𝗿𝘀. 𝗚𝗲𝘁 𝘁𝗵𝗲 𝗚𝘂𝗶𝗱𝗲 𝗵𝗲𝗿𝗲 - https://lnkd.in/gJWSVKNM 𝗠𝗮𝗿𝗰𝗵 𝗱𝗶𝘀𝗰𝗼𝘂𝗻𝘁 𝗲𝗻𝗱𝗶𝗻𝗴 𝘁𝗼𝗱𝗮𝘆 - AZURE30 / AWS30 / GCP30 only for next 5 people If you've read so far, do LIKE and RESHARE the post👍
Choose a format for your next LinkedIn collaboration.
A dedicated post to introduce your brand to my audience.
Your collaboration, managed on Naano
How does this price compare? B2B creator rates 2026
Based on 217 people who reacted to or commented on my posts. Percentages use the profiles that could be classified.
Based on 217 people who reacted to or commented on my posts. Percentages use the profiles that could be classified.
Based on 217 people who reacted to or commented on my posts. Percentages use the profiles that could be classified.
Based on 217 people who reacted to or commented on my posts. Percentages use the profiles that could be classified.
Storefront by Naano · Create yours
Shubham Wadekar is a B2B LinkedIn creator based in India with 318,164 followers, posting about AI, Software, and EdTech. On Naano, one sponsored LinkedIn post by Shubham Wadekar costs €575, a fixed price per post.
The Naano team casts the creators, writes the briefs, reviews every draft with you and reports results per creator. You approve the shortlist and every draft.